在线AI教程 / AI上云
[Amazon Bedrock] 使用 AWS CDK 编排 SageMaker AI 端点的自动扩缩容
人工智能 使用 AWS CDK 编排 SageMaker AI 端点的自动扩缩容 更新 Amazon SageMaker AI 实时端点配置(更改实例类型、实例数量或环境变量)会导
人工智能
使用 AWS CDK 编排 SageMaker AI 端点的自动扩缩容
更新 Amazon SageMaker AI 实时端点配置(更改实例类型、实例数量或环境变量)会导致通过 AWS CloudFormation 或 AWS Cloud Development Kit(AWS CDK)进行的部署失败。SageMaker AI 要求你在更新端点之前注销可扩缩目标(scalable target),但一旦注销,CloudFormation 就无法跟踪 AWS Application Auto Scaling 资源。
在本文中,我们展示如何使用一个可复用的 CDK 构造(construct)配合 AWS CloudFormation 自定义资源,在端点更新期间自动编排注销与注册自动扩缩容。你可以在一次部署中同时更新端点配置和自动扩缩容参数,无需人工介入。
为什么会出现这个问题
当你用原生 CloudFormation 自动扩缩容资源部署一个 SageMaker AI 端点,然后更改端点配置并重新部署时,会出现若干种失败模式。具体失败取决于你改了什么,以及你如何绕过这个问题。
在自动扩缩容仍注册的情况下更改端点配置
CloudFormation 试图在可扩缩目标仍处于注册状态时更新端点。SageMaker AI 会以如下错误拒绝该更新:
The variant(s) "[AllTraffic]" must be deregistered as scalable targets with Application Auto Scaling before they can be removed or have their instance type updated.
SageMaker AI 在 CloudFormation 触及自动扩缩容资源之前就阻止了端点更新。
手动注销自动扩缩容,然后只更改端点配置
如果你通过 AWS Command Line Interface(AWS CLI)注销可扩缩目标,然后仅以端点配置变更重新部署,部署会成功。然而,尽管自动扩缩容就在 CloudFormation 模板中,CloudFormation 并不会注册它。因为 CloudFormation 模板中的自动扩缩容参数没有变化,CloudFormation 既不会注册可扩缩目标,也不会重新应用扩缩容策略。此时端点在没有自动扩缩容的情况下运行,而且没有任何错误提示表明出了问题。
手动注销自动扩缩容,然后更改自动扩缩容参数
如果你通过 AWS CLI 注销可扩缩目标,然后带着自动扩缩容参数变更重新部署,CloudFormation 会试图更新那个已不存在的 ScalableTarget 资源:
Resource of type 'AWS::ApplicationAutoScaling::ScalableTarget' with identifier 'endpoint/
这个失败值得注意,因为回滚也会失败(UPDATE_ROLLBACK_FAILED),使堆栈处于损坏状态,需要在 CloudFormation 控制台手动干预才能恢复。
解决方案概述
你可以使用这个 CDK 构造,用三个自定义资源替换原生的 AWS::ApplicationAutoScaling::ScalableTarget 和 AWS::ApplicationAutoScaling::ScalingPolicy CloudFormation 资源。这些自定义资源围绕端点更新执行注销和注册自动扩缩容,并通过 CDK 中的 node.add_dependency 调用强制实施显式的依赖顺序。完整顺序如下:
Deregister(注销)(自定义资源):在端点更新开始前移除可扩缩目标。首次部署时尚不存在可扩缩目标,因此处理程序会优雅地处理该错误并继续。 Endpoint update(端点更新)(由 CDK 管理):CDK 正常更新端点资源,切换到新的端点配置。 Register Scalable Target(注册可扩缩目标)(自定义资源):等待端点达到 InService 状态,然后注册可扩缩目标。 Attach Scaling Policy(挂载扩缩容策略)(自定义资源):等待可扩缩目标可被查询,然后应用目标跟踪策略。
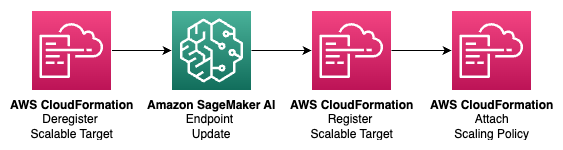
图 1:围绕由 CDK 管理的端点更新,用自定义资源编排 SageMaker AI 端点自动扩缩容。
Register Scalable Target 和 Attach Scaling Policy 使用 CDK provider 的异步完成模式。每个自定义资源都有一个 on_event 处理程序(立即返回)和一个 is_complete 处理程序。provider 的 waiter 会按固定间隔(每 30 秒)重新调用 is_complete 处理程序,直到其就绪检查通过。provider 的 total_timeout(Register Scalable Target 为 1 小时,Attach Scaling Policy 为 15 分钟)限定了等待的上限,因此等待不受任何单次 Lambda 调用超时的限制。
每个自定义资源上的 ConfigHash 属性会强制 CloudFormation 在任一配置值变化时重新调用 Lambda 函数。端点配置和自动扩缩容参数被放在一起定义,因为单个 ConfigHash 驱动整个自动扩缩容编排。
虽然该构造只定义了三个自定义资源,但部署后的堆栈包含不止三个 Lambda 函数。每个自定义资源都由一个 CDK cr.Provider 支撑,而 provider 框架会生成自己的辅助 Lambda 函数。同步 provider(Deregister)会额外增加一个框架函数。异步 provider(Register Scalable Target 和 Attach Scaling Policy)会额外增加三个(onEvent、isComplete 和 onTimeout),再加一个驱动 waiter 的 AWS Step Functions 状态机。因此,部署后的堆栈包含三个自定义资源、两个 Step Functions 状态机和十二个 Lambda 函数。其中五个资源承载该构造自己的处理程序代码(Deregister 一个,每个异步资源各有一对 on_event 和 is_complete),其余七个由 provider 框架生成。你不需要编写或维护框架生成的函数,但它们确实存在于堆栈中,在审阅已部署资源时值得计入。
演练
在本演练中,你使用提供的示例堆栈部署一个带自动扩缩容的 SageMaker AI 端点,然后验证配置更新能否正常工作。
该演练包含以下步骤:
克隆仓库并安装依赖。 配置你的端点和自动扩缩容设置。 部署并验证。 测试一次更新。
源代码位于链接的 GitHub 仓库中。
先决条件
本次演练你需要以下内容:
一个 AWS 账户,具备 Amazon SageMaker AI、AWS Lambda、AWS Identity and Access Management(IAM)、Application Auto Scaling 和 Amazon CloudWatch 的权限。 已安装 AWS CDK v2。 Python 3.12 或更高版本。 用于 Python 依赖管理的 uv。 Amazon Simple Storage Service(Amazon S3)中的 SageMaker AI 模型产物和 Amazon Elastic Container Registry(Amazon ECR)中的容器镜像,或者 SageMaker AI 内置算法容器。
克隆仓库并安装依赖
克隆仓库: git clone cd sample-sagemaker-endpoint-autoscaling 安装依赖: uv sync
配置你的端点和自动扩缩容设置
端点和自动扩缩容设置一起定义在 config/config.yaml 中,因为单个 config_hash 驱动整个自动扩缩容编排。改动其中任一部分都会触发完整的编排序列。
用你的值编辑 config/config.yaml:
endpoint: endpoint_name: "my-model-endpoint" image: "123456789012.dkr.ecr.us-east-1.amazonaws.com/my-model:latest" model_data_url: "s3://my-bucket/models/model.tar.gz" instance_type: "ml.m5.large" initial_instance_count: 1 environment: {} autoscaling: min_capacity: 1 max_capacity: 10 target_value: 100 scale_in_cooldown: 600 scale_out_cooldown: 120
端点参数对应 SageMaker AI 的 CreateModel 和 CreateEndpointConfig API。自动扩缩容参数对应 Application Auto Scaling 的 RegisterScalableTarget 和 PutScalingPolicy API。
部署并验证
如果尚未完成,先引导(bootstrap)你的 AWS 环境: uv run cdk bootstrap 部署堆栈: uv run cdk deploy InferenceStack
CloudFormation 会创建 SageMaker AI 模型、端点配置和端点,然后按顺序运行三个自定义资源来注册自动扩缩容。
验证部署已注册可扩缩目标: aws application-autoscaling describe-scalable-targets --service-namespace sagemaker --resource-ids endpoint/my-model-endpoint/variant/AllTraffic 验证部署已应用扩缩容策略: aws application-autoscaling describe-scaling-policies --service-namespace sagemaker --resource-id endpoint/my-model-endpoint/variant/AllTraffic
测试一次更新
更改 config/config.yaml 中的一个值,例如把实例类型从 ml.m5.large 改为 ml.m5.xlarge,然后重新部署:
uv run cdk deploy InferenceStack
部署完成后,验证自动扩缩容仍处于注册状态且已带上更新后的值:
aws application-autoscaling describe-scalable-targets --service-namespace sagemaker --resource-ids endpoint/my-model-endpoint/variant/AllTraffic
与现有堆栈集成
如果你是全新开始,或者想要一个参考实现,请使用示例堆栈。如果你已经有包含 SageMaker AI 资源的 CDK 堆栈,可以直接使用该构造。
要与现有堆栈集成,把 sagemaker_autoscaling/constructs/ 目录复制到你的项目中,并在端点资源旁边加入该构造:
import json from sagemaker_autoscaling.constructs.sagemaker_autoscaling_construct import ( AutoscalingConfig, SagemakerAutoscalingConstruct, SagemakerAutoscalingProps, )
Both endpoint and auto scaling values must be in config_hash so that
a change to either triggers the auto scaling orchestration.
config_hash = json.dumps({ "endpoint": { "image": "123456789012.dkr.ecr.us-east-1.amazonaws.com/my-model:latest", "modelDataUrl": "s3://my-bucket/models/model.tar.gz", "instanceType": "ml.m5.large", "initialInstanceCount": 1, }, "autoscaling": { "minCapacity": 1, "maxCapacity": 10, "targetValue": 100, "scaleInCooldown": 600, "scaleOutCooldown": 120, }, })
SagemakerAutoscalingConstruct( self, "Autoscaling", props=SagemakerAutoscalingProps( endpoint=your_endpoint, # your CfnEndpoint autoscaling=AutoscalingConfig( min_capacity=1, max_capacity=10, target_value=100, scale_in_cooldown=600, scale_out_cooldown=120, ), config_hash=config_hash, ), )
该构造如何工作
本节介绍 SagemakerAutoscalingConstruct 的关键实现细节。
Deregister(注销)
Deregister 自定义资源在端点更新之前调用 deregister_scalable_target。它针对首次部署(此时还没有可扩缩目标)处理 ObjectNotFoundException:
def handler(event, context): resource_id = event["ResourceProperties"]["ResourceId"] if event["RequestType"] in ("Create", "Update"): try: client.deregister_scalable_target( ServiceNamespace="sagemaker", ResourceId=resource_id, ScalableDimension="sagemaker:variant:DesiredInstanceCount", ) except client.exceptions.ObjectNotFoundException: pass # No scalable target on first deploy return {"PhysicalResourceId": f"deregister-{resource_id}"}
依赖关系在 CDK 中建立:
props.endpoint.node.add_dependency(deregister)
Register Scalable Target(注册可扩缩目标)
尽管一旦更新被接受,CloudFormation 就把端点资源视为完成,但可扩缩目标只能在端点达到 InService 之后才能注册。Register Scalable Target 不是在单次 Lambda 调用中阻塞等待,而是使用 provider 的异步完成模式。on_event 处理程序立即返回,provider 的 waiter 按 query_interval 重新调用 is_complete 处理程序,直到端点处于 InService。provider 的 total_timeout(1 小时)限定等待上限,而不是任何单次 Lambda 调用的超时:
def handler(event, context): props = event["ResourceProperties"] resource_id = props["ResourceId"] endpoint_name = resource_id.split("/")[1] if event["RequestType"] == "Delete": return {"IsComplete": True} status = sm_client.describe_endpoint(EndpointName=endpoint_name)["EndpointStatus"] if status == "Failed": raise Exception("Endpoint in Failed state") if status != "InService": return {"IsComplete": False} as_client.register_scalable_target( ServiceNamespace="sagemaker", ResourceId=resource_id, ScalableDimension="sagemaker:variant:DesiredInstanceCount", MinCapacity=int(props["MinCapacity"]), MaxCapacity=int(props["MaxCapacity"]), ) return {"IsComplete": True}
在堆栈删除时,on_event 处理程序会注销可扩缩目标以进行清理。
Attach Scaling Policy(挂载扩缩容策略)
在 RegisterScalableTarget 返回之后,有一小段时间窗口内目标尚不可查询。Attach Scaling Policy 使用同样的异步完成模式:on_event 处理程序立即返回,is_complete 处理程序只有在可扩缩目标可查询时才报告完成,此时它会应用策略。provider 的 total_timeout(15 分钟)限定等待上限:
def handler(event, context): props = event["ResourceProperties"] resource_id = props["ResourceId"] if event["RequestType"] == "Delete": return {"IsComplete": True} resp = client.describe_scalable_targets( ServiceNamespace="sagemaker", ResourceIds=[resource_id], ScalableDimension="sagemaker:variant:DesiredInstanceCount", ) if not resp.get("ScalableTargets"): return {"IsComplete": False} client.put_scaling_policy( PolicyName=props["PolicyName"], ServiceNamespace="sagemaker", ResourceId=resource_id, ScalableDimension="sagemaker:variant:DesiredInstanceCount", PolicyType="TargetTrackingScaling", TargetTrackingScalingPolicyConfiguration=json.loads(props["ScalingPolicyConfig"]), ) return {"IsComplete": True}
在堆栈删除时,on_event 处理程序会删除扩缩容策略以进行清理。
清理
为避免产生后续费用,请删除这些资源:
uv run cdk destroy InferenceStack
这会移除 SageMaker AI 端点、端点配置、模型、Lambda 函数、IAM 角色、由目标跟踪扩缩容策略创建的 Amazon CloudWatch 告警,并注销可扩缩目标。
结论
在本文中,我们展示了如何使用一个可复用的 CDK 构造自动注销和注册自动扩缩容,从而编排 SageMaker AI 端点更新。该构造使用三个 CloudFormation 自定义资源,配合显式的依赖顺序和 ConfigHash 属性,让自动扩缩容在多次部署之间保持完好。
要开始使用,请克隆 sample-sagemaker-endpoint-autoscaling 仓库并按照设置说明操作。该仓库包含一个可以直接部署的示例堆栈,你也可以把该构造集成到你现有的 CDK 堆栈中。
关于 SageMaker AI 的 Application Auto Scaling 的更多信息,请参阅自动扩缩 Amazon SageMaker AI 模型。关于 CloudFormation 自定义资源的更多信息,请参阅 AWS CloudFormation 用户指南中的自定义资源。
关于作者